Joseph Noto's Portfolio
Technical News Search Engine
Overview
In this project, I built a Java-based, in-memory search engine to process and analyze 100 different technology-related news articles. The program was built entirely in Eclipse as a Maven project. This program focused on applying object-oriented programming, different data structures, and n-tier architecture to organize article data and support fast analytical queries. The different data structures included a CSV parser, an inverted index, and a TreeMap implementation. A user-interface was built on top of this program to enable users to choose between an interactive menu and a command mode to analyze the data. A logging system was also built to keep record of all actions the search engine takes, and to flag any errors that may occur in runtime.
Project Goals
- Process and organize technology-related articles from CSV and JSON formats
- Implement object-oriented programming across a clearly separated system architecture
- Enable users to search and analyze article data efficiently
- Generate statistics and insights from the dataset, including trending topics over time
- Provide both a guided and command-line interface for querying the data
Functionality
- Keyword search across articles using an inverted index
- Autocomplete suggestions using a Trie implementation
- Trending topic analysis for the top 10 words used in a given month
- Topic popularity trends across a specified date range
- Article browsing by date range, sorted chronologically
- Article lookup by unique ID
- General database statistics
- All functionality accessible through either an interactive menu or a direct command line-style interface
Technical Implementation
- Parses articles from CSV or JSON files, then indexes them. The inverted index was made using a HashMap, making keyword lookups run in constant time.
- Powers the core commands necessary for program functionality. Uses a Trie for autocomplete, a TreeMap for date-range queries, and a PriorityQueue to maintain the top 10 trending topics in the dataset.
- Interactive and command mode interfaces both route through the same shared logic layer, so the commands behave the same regardless of which interface the user selects.
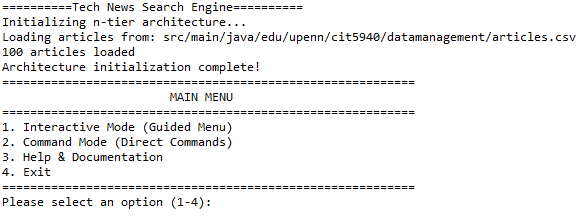
Program verifies that articles were successfully loaded and parsed before menu loads.
The logging system was designed so that every part of the program would write to the same log instance. The user-interface was designed so that both the interactive and command modes could call the same command logic without duplicating code.
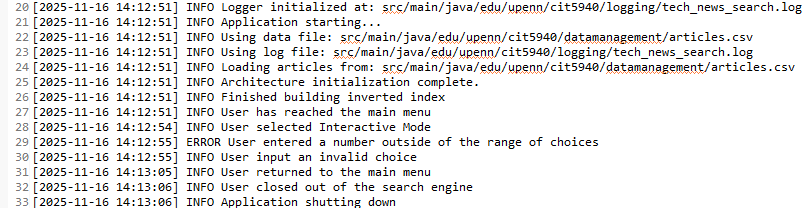
Log file takes note of all actions user takes and identifies the source of any errors the user may encounter
Results
The search engine loads and indexes articles from either file format, skipping and logging malformed records instead of crashing. Beyond retrieving the data, the topics and trends commands turn the article set into relevant analysis, as the user is able to uncover which subjects dominate technical news coverage in a given month and track how a topic’s popularity shifted over time.
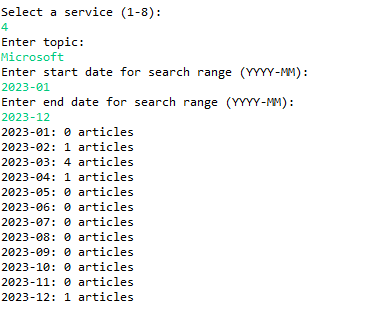
Searching for articles involving Microsoft in 2023 reveal an increase in articles covering the company between February and April 2023, with peak in March
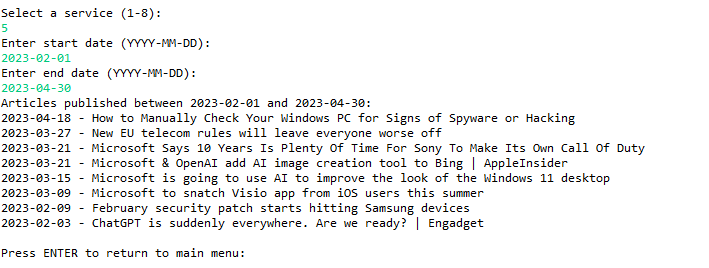
Searching for specific articles within that range allows users to see news driving the increase in Microsoft articles.
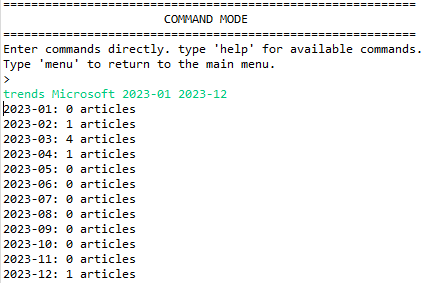
Typing in a direct command achieves the same result!
Technologies
- Java
- Object-Oriented Programming
- Data Structures
- Eclipse
- Maven
Key Takeaways
Working through this project offered an insightful look under the hood of what it actually takes to analyze data at scale. I came away with a much deeper appreciation for how much the right data structure matters for real-world performance. Many of the structures used here were pulled directly from earlier assignments throughout my Data Structures course, which made this project feel like a genuine culmination of everything I had learned up to that point.
Beyond the technical implementation, this project gave me a clearer sense of everything that happens behind the scenes to make efficient analysis possible in the first place. To build this further, I’d be interested in testing the system against larger datasets spanning multiple years and/or topics to see how well the current architecture holds up under more varied inputs.